
https://raw.githubusercontent.com/OrcVole/crawl4ai-cloudron/main/CloudronVersions.json
Description
0.9.4
Crawl4AI
Crawl4AI is an open-source web crawling and extraction API, built to feed clean data into language models or automation workflows. It fetches a page with a real Chromium headless browser and returns the content as clean Markdown, raw HTML, a screenshot, or a PDF. The package exposes both a REST API and an MCP endpoint, so AI agent tools can call it directly.
Every request requires an API token, generated automatically the first time the app starts. There is no way to use the service without it. Because the browser runs inside a container, its own security sandbox cannot be enabled; this is the same situation every headless-browser app on Cloudron is in (browserless included). The package compensates: the token is required on every call, requests to addresses inside your server's own private network are refused by default, and optional scripting hooks are disabled.
Nothing here needs backing up beyond the API token itself: there is no separate database, and crawl results are not kept.
This package includes software developed by UncleCode as part of the Crawl4AI project, licensed Apache-2.0 with an attribution requirement (see NOTICE). It is a community package, not affiliated with or officially supported by the Crawl4AI project.
Recent Changes
Update Crawl4AI to 0.9.4, a security release: it closes two SSRF paths that bypassed the
server's egress controls, and a trust-boundary bypass that could expose server environment
variables to an API client. Updating is recommended.
The app icon is now Crawl4AI's own mark, taken from the project's wordmark, replacing a
placeholder.
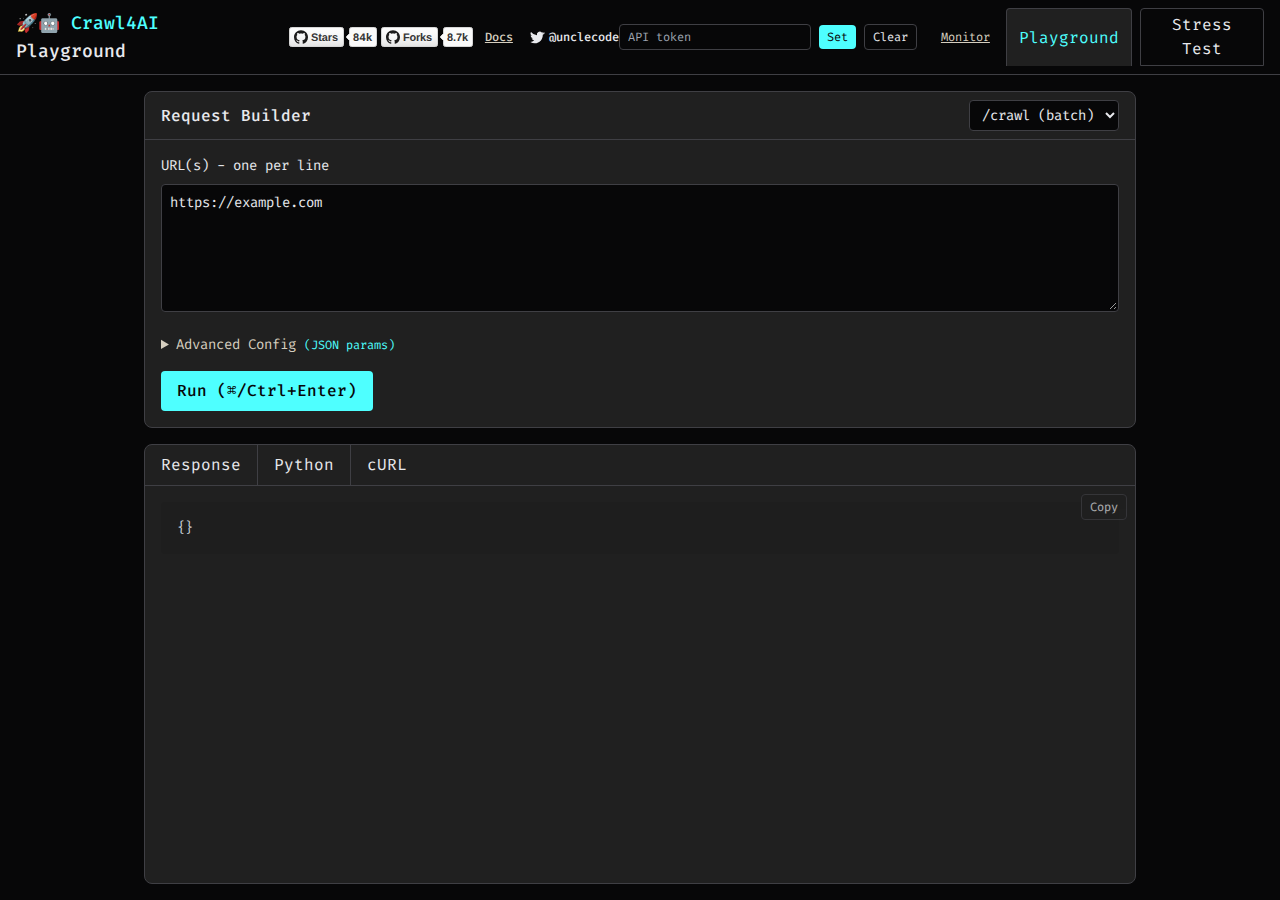
The store listing now shows a real screenshot instead of a placeholder.
Rebuilt on
cloudron/base:5.1.0(was5.0.0); no functional change, a newer Ubuntu 24.04 pointrelease with more OS security patches.